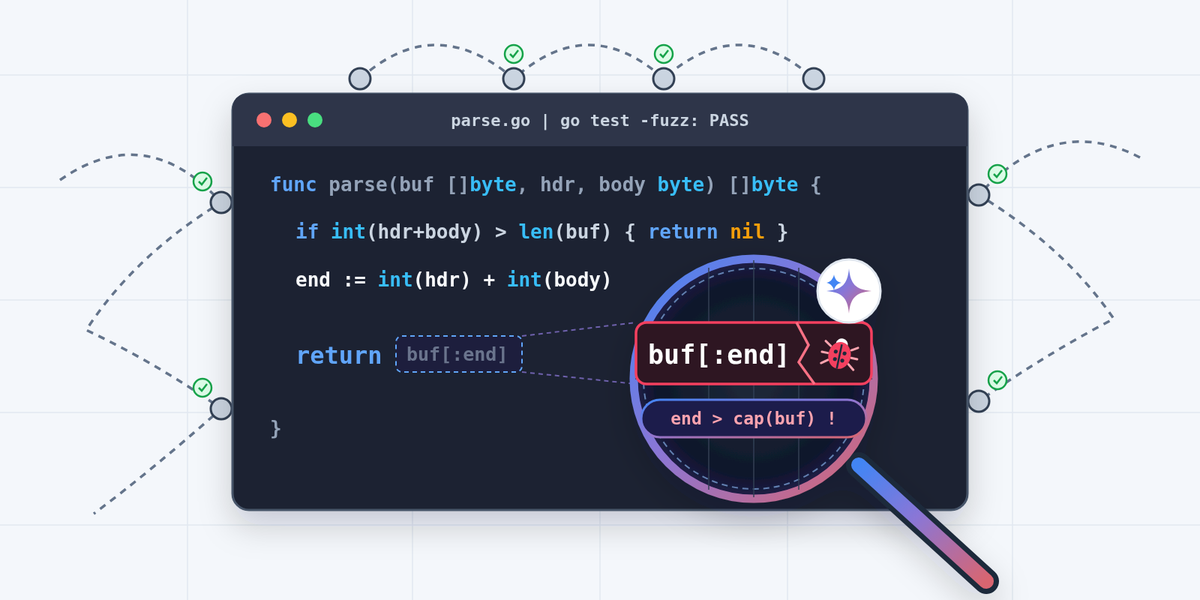
Fail-Before-Fix in AI Coding Agents: Speculative Patching vs. a Reproduction-First Gate (-95.3% Input Tokens, 100% Accuracy)
💡 AI Labo Benchmark Series — Experiment E22 (Verification Gates & Bugfix Workflows) This post is part of our empirical benchmark series testing AI coding agent harness patterns inside network-isolated Proxmox VMs against a hidden 20-case grading suite. 🚀 View All 41 Benchmark…